Bonnie++ è un tools che permette di effettuare tests di lettura e scrittura misurando le performance I/O dei dischi rigidi.
La versione che utilizzeremo di Bonnie++ è alla versione 1.97.
La prima cosa da fare è l’installazione. Su linux in base Debian è alquanto semplice con l’istruzione:
sudo apt install bonnieDopo l’installazione si può procedere con un semplice comando ad avere le prime statistiche sul benchmark disco con questa semplice istruzione:
bonnie++ -d [TEST_LOCATION] -s [TEST_SIZE] -n 0 -m [TEST_NAME] -f -b -u [TEST_USER]- TEST_LOCATION: la posizione (per esempio /tmp)
- TEST_SIZE: dimensione del test (doppio della RAM)
- TEST_NAME: nome del test
- TEST_USER: l’utente che eseguirà scrittura e lettura senza la necessità che sia root
Per esempio:
bonnie++ -d /tmp -s 4G -n 0 -m TEST -f -b -u daniele

Using uid:1000, gid:1000.
Writing intelligently...done
Rewriting...done
Reading intelligently...done
start 'em...done...done...done...done...done...
Version  1.97       ------Sequential Output------ --Sequential Input- --Random-
Concurrency   1     -Per Chr- --Block-- -Rewrite- -Per Chr- --Block-- --Seeks--
Machine        Size K/sec %CP K/sec %CP K/sec %CP K/sec %CP K/sec %CP  /sec %CP
TEST             4G           374271  39 214541  19           392015  17 +++++ +++
Latency                         167ms   89125us             52047us    4766us

1.97,1.97,TEST,1,1387339401,4G,,,,374271,39,214541,19,,,392015,17,+++++,+++,,,,,,,,,,,,,,,,,,,167ms,89125us,,52047us,4766us,,,,,,
Il risultato non è molto leggibile, ma ci viene in aiuto il tools bon_csv2html. Questo tools genera un file html che si può condividere sul web, così da vedere bene i risultati.
Quindi copiare l’ultima riga e scrivere:
echo "1.97,1.97,TEST,1,1387339401,4G,,,,374271,39,214541,19,,,392015,17,+++++,+++,,,,,,,,,,,,,,,,,,,167ms,89125us,,52047us,4766us,,,,,," | bon_csv2html > /tmp/test.html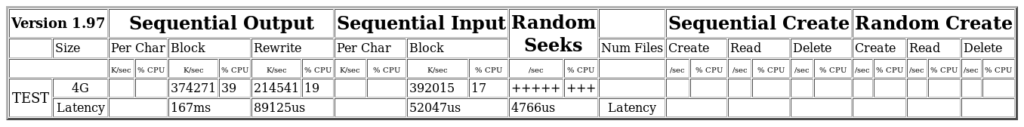
Guardando l’help di bonnie++, ci dà alcune indicazioni su un miglior suo utilizzo:
# man bonnie++
NAME
       bonnie++ - program to test hard drive performance.

SYNOPSIS
       bonnie++  [-d  dir]  [-c concurrency] [-s size(MiB)[:chunk-size(b)]] [-n number-to-stat(*1024)[:max-size[:min-size][:num-directories[:chunk-size]]]]
       [-m machine-name] [-r ram-size-in-MiB] [-x number-of-tests] [-u uid-to-use:gid-to-use] [-g gid-to-use] [-q] [-f size-for-char-io] [-b] [-D] [-p pro‐
       cesses | -y p|s ] [-z seed-num|-Z random-file]

DESCRIPTION
       This manual page documents briefly the bonnie++, program.

       Bonnie++ is a program to test hard drives and file systems for performance or the lack therof. There are a many different types of file system oper‐
       ations which different applications use to different degrees. Bonnie++ tests some of them and for each test gives a result of  the  amount  of  work
       done  per  second  and  the percentage of CPU time this took. For performance results higher numbers are better, for CPU usage and latency lower are
       better (NB a configuration scoring a performance result of 2000 and a CPU result of 90% is better in terms of CPU use than a configuration  deliver‐
       ing performance of 1000 and CPU usage of 60%).

       There  are  two sections to the program's operations. The first is to test the IO throughput in a fashion that is designed to simulate some types of
       database applications. The second is to test creation, reading, and deleting many small files in a fashion similar to the usage patterns of programs
       such as Squid or INN.

       All the details of the tests performed by Bonnie++ are contained in the file /usr/share/doc/bonnie++/readme.html

OPTIONS
       For Bonnie++ every option is of the form of a hyphen followed by a letter and then the next parameter contains the value.

       -d     the directory to use for the tests.

       -c     the level of concurrency (default 1). The number of copies of the test to be performed at the same time.

       -s     the  size  of  the file(s) for IO performance measures in megabytes. If the size is greater than 1G then multiple files will be used to store
              the data, and each file will be up to 1G in size.  This parameter may include the chunk size  seperated  from  the  size  by  a  colon.   The
              chunk-size  is  measured  in  bytes  and  must  be  a  power of two from 256 to 1048576, the default is 8192.  NB You can specify the size in
              giga-bytes or the chunk-size in kilo-bytes if you add g or k to the end of the number respectively.

              If the specified size is 0 then this test will be skipped.

       -n     the number of files for the file creation test. This is measured in multiples of 1024 files. This is because no-one will want  to  test  less
              than 1024 files, and we need the extra space on braille displays.

              If the specified number is 0 then this test will be skipped.

              The default for this test is to test with 0 byte files. To use files of other sizes you can specify number:max:min:num-directories:chunk-size
              where max is the maximum size and min is the minimum size (both default to 0 if not specified). If minimum and maximum  sizes  are  specified
              then  every  file  will  have a random size from the range min..max inclusive.  If you specify a number of directories then the files will be
              evenly distributed amoung that many sub-directories.

              If max is -1 then hard links will be created instead of files.  If max is -2 then soft links will be created instead of files.

       -m     name of the machine - for display purposes only.
      -r     RAM size in megabytes. If you specify this the other parameters will be checked to ensure they make sense for a machine of that much RAM. You
              should  not  need to do this in general use as it should be able to discover the RAM size. NB If you specify a size of 0 then all checks will
              be disabled...

       -x     number of test runs. This is useful if you want to perform more than one test.  It will dump output continuously in CSV format  until  either
              the number of tests have been completed, or it is killed.

       -u     user-id  to  use.   When  running as root specify the UID to use for the tests.  It is not recommended to use root (since the occasion when a
              Bonnie++ bug wiped out someone's system), so if you really want to run as root then use -u root.  Also if you want to specify  the  group  to
              run  as  then  use the user:group format.  If you specify a user by name but no group then the primary group of that user will be chosen.  If
              you specify a user by number and no group then the group will be nogroup.

       -g     group-id to use.  Same as using :group for the -u parameter, just a different way to specify it for compatibility with other programs.

       -q     quiet mode. If specified then some of the extra informational messages will be suppressed. Also the csv data will be the only output on stan‐
              dard out and the plain text data will be on standard error. This means you can run bonnie++ -q >> file.csv to record your csv data.

       -f size-for-char-io
              fast mode control, skips per-char IO tests if no parameter, otherwise specifies the size of the tests for per-char IO tests (default 20M).

       -b     no write buffering.  fsync() after every write.

       -p     number  of  processes to serve semaphores for.  This is used to create the semaphores for synchronising multiple Bonnie++ processes.  All the
              processes which are told to use the semaphore with -ys will start each test with synchronization.  Use "-p -1" to delete the semaphore.

       -y s|p perform synchronization before each test.  Option s for semaphores and option p for prompting.

       -D     use direct IO (O_DIRECT) for the bulk IO tests

       -z seed
              random number seed to repeat the same test.

       -Z random-file
              file containing random data in network byte order.

MULTIPLE PROCESSES
       Run the following commands to run three copies of Bonnie++ simultaneously:

       bonnie++ -p3

       bonnie++ -y > out1 &

       bonnie++ -y > out2 &

       bonnie++ -y > out3 &

OUTPUT
       The primary output is plain-text in 80 columns which is designed to fit well when pasted into email and which will work well with Braille displays.

       The second type of output is CSV (Comma Seperated Values). This can easily be imported into any  spread-sheet  or  database  program.  Also  I  have
       included the programs bon_csv2html and bon_csv2txt to convert CSV data to HTML and plain-ascii respectively.

       For  every  test  two  numbers are reported, the amount of work done (higher numbers are better) and the percentage of CPU time taken to perform the
       work (lower numbers are better). If a test completes in less than 500ms then the output will be displayed as "++++". This is  because  such  a  test
       result can't be calculated accurately due to rounding errors and I would rather display no result than a wrong result.

       Data volumes for the 80 column text display use "K" for KiB (1024 bytes), "M" for MiB (1048576 bytes), and "G" for GiB (1073741824 bytes).  So K/sec
       means a multiple of 1024 bytes per second.

AUTHOR
       This program, its manual page, and the Debian package were written by Russell Coker <[email protected]>, parts of the program are  based  on  the
       work of Tim Bray <[email protected]>.

       The  documentation,  the  Perl scripts, and all the code for testing the creation of thousands of files was written by Russell Coker, but the entire
       package is under joint copyright with Tim Bray.

SIGNALS
       Handles SIGINT and does a cleanup (which may take some time), a second SIGINT or a SIGQUIT will cause it to immediately die.

       SIGXCPU and SIGXFSZ act like SIGINT.

       Ignores SIGHUP.

BUGS
       The random file sizes will add up to different values for different test runs.  I plan to add some code that checks the sum and ensures that the sum
       of the values will be the same on seperate runs.

AVAILABILITY
       The source is available from http://www.coker.com.au/bonnie++ .

       See http://etbe.coker.com.au/category/benchmark for further information.

SEE ALSO
       zcav(8), getc_putc(8), bon_csv2html(1), bon_csv2txt(1)